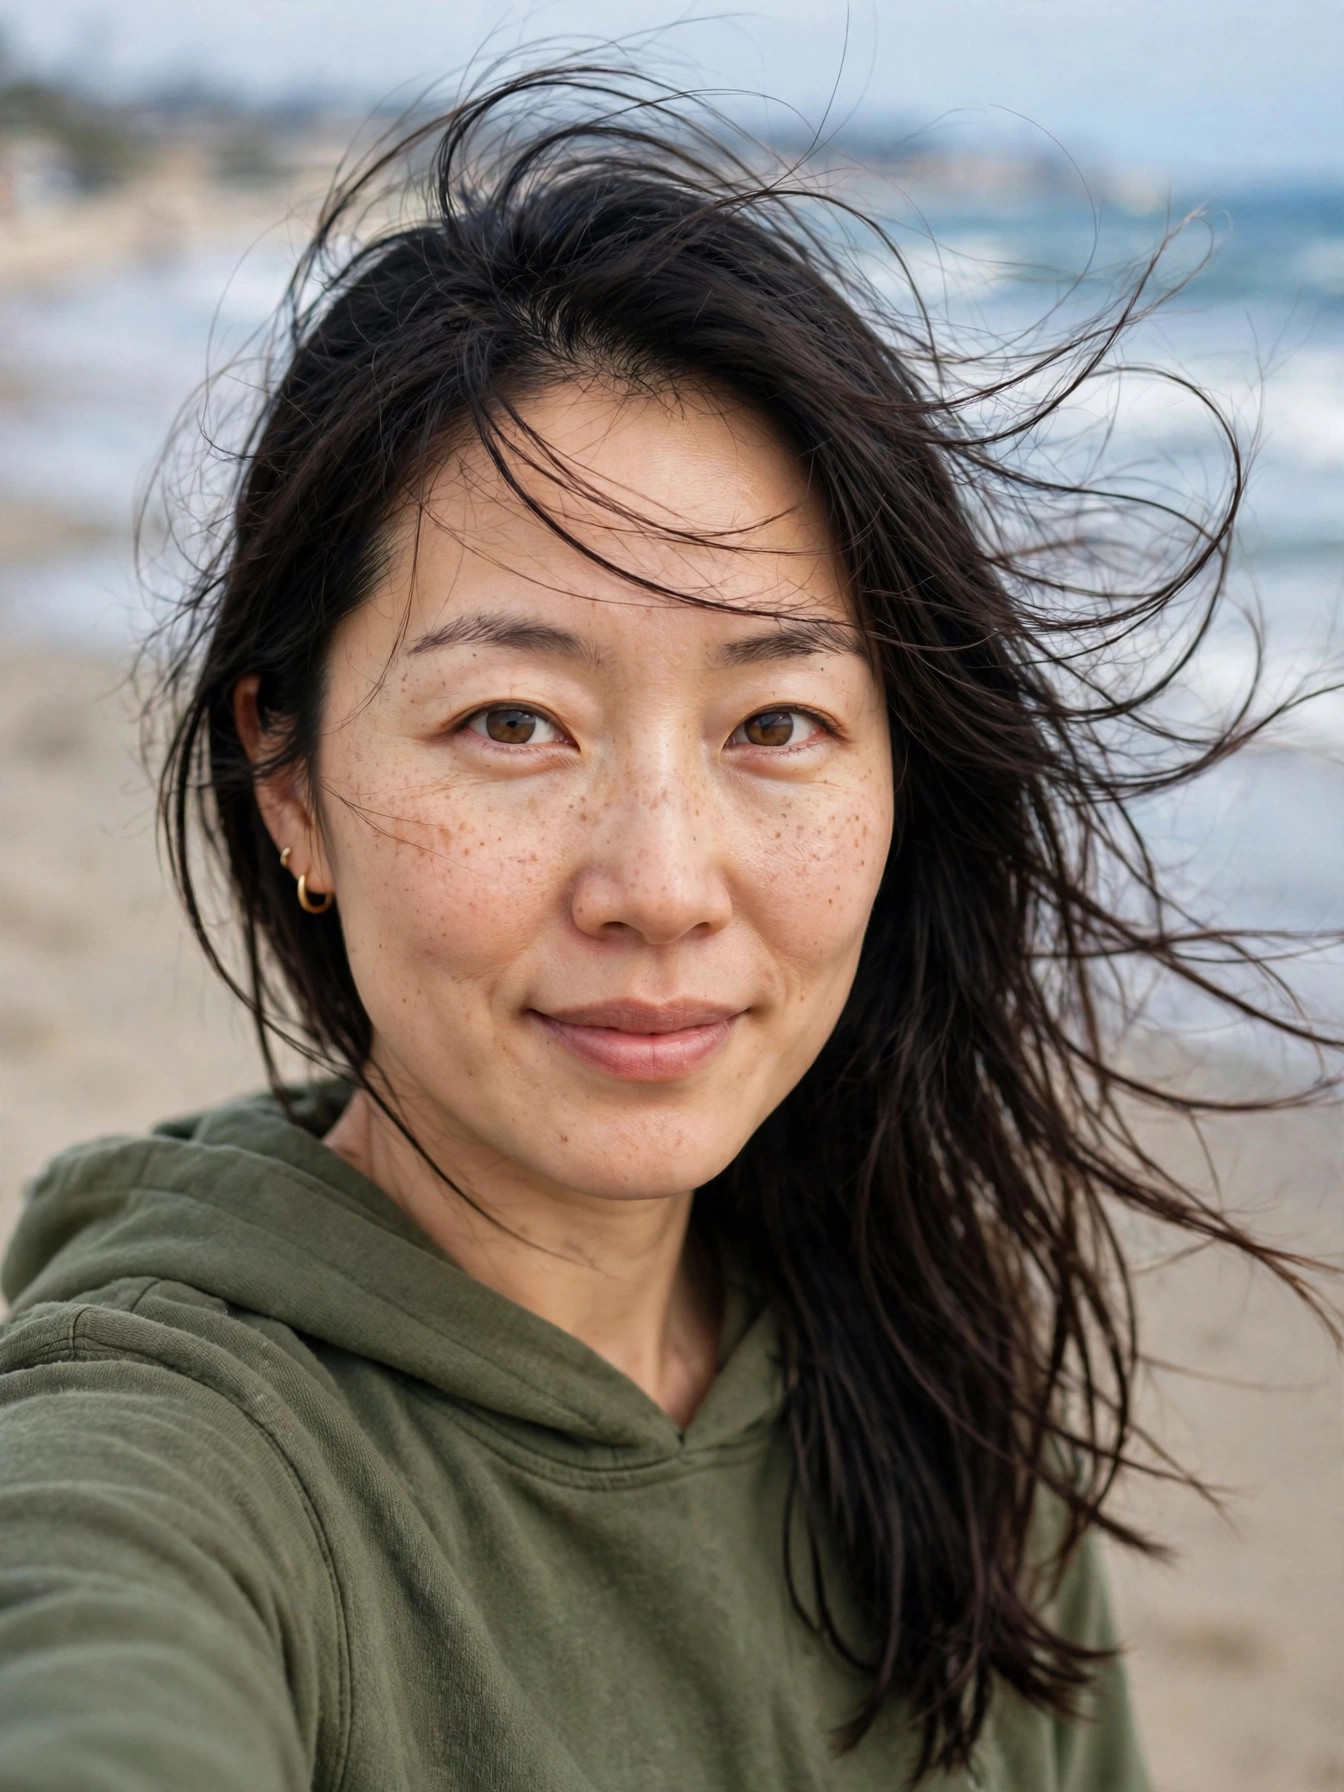
Imagine a video call where everything feels ordinary: the other person blinks, breathes, leans in, interrupts you mid-sentence, and laughs at the right moments. Now imagine learning afterward that there was no other person. That is the scenario Bay Area startup Tavus described this month when it unveiled Griffin, a new AI model the company calls its first Human Interaction Model. According to Tavus, 48 percent of the 54 people who held a live video conversation with a Griffin-powered avatar believed they were talking to a real human. Previous systems, the company says, convinced fewer than 3 percent.
Griffin is not a chatbot with a face pasted on. It is built for full-duplex, face-to-face conversation: it listens to speech, watches visual cues, and responds with a human-like voice, facial expressions, and gestures, all in real time. Tavus announced the model on X on October 1, and the claim that followed has ricocheted around tech media ever since: the first model, the company says, to pass the video Turing test.
What the test actually showed
The experiment, as described in Tavus's announcement and later independent analysis, was simple. Fifty-four participants were recruited through an independent research platform and told they would be matched with another participant for a one-minute call about what they were looking forward to this year. Their partner was actually a photorealistic avatar powered by Griffin-Lite, generating face, voice, and replies live. Only after the call were participants asked whether it had ever crossed their mind that the partner might not be a person. Twenty-six of them, 48 percent, said they believed it was a real human. Those who were fooled were 79 percent confident in that judgment on average, nearly matching the 81 percent confidence of those who correctly spotted the bot. A control run using an older stack, Phoenix 4.5 with Sparrow-2 and Raven-1, convinced just 1 of 41 participants, or 2.4 percent. The ratings tell their own story: participants scored Griffin 5.4 out of 7 for naturalness and 5.6 for trustworthiness, but only 4.9 for conversation flow, the lowest of the five measures. Those who grew suspicious usually did so within the first 20 seconds, and more than half of all participants said the possibility that the partner was AI never crossed their mind during the call.
That is a striking result, and it deserves the caveats. This was a short, friendly, company-run study, not an adversarial test. Nobody was trying to catch the avatar; nobody was asking gotcha questions or staring at its hands for a full minute looking for rendering glitches. Treating 26 out of 54 on this protocol as a universal pass of the Turing test would be a mistake. Think of it instead as a measurement of first-impression realism in low-suspicion conditions, and on that measure, Griffin is a leap beyond anything published before it.
How Griffin works
Enjoying this story?
Get the five most important stories in tech, every morning. Free.
Under the hood, Griffin does something earlier avatar systems did not. According to Tavus, the model generates every pixel of every video frame in real time from a single reference image. That includes not just the face, but the arms and fingers, the movement of the chair, the shadows it casts, and the background. The avatars appear to breathe and blink naturally, and they react in real time: the model can interrupt a person, be interrupted without losing its train of thought, and change subjects mid-conversation. Tavus chief executive Hassaan Raza put the design philosophy simply: humans are evolutionarily designed to communicate face to face, through expressions, tone, gestures, and timing, and Griffin is built to handle that layer, not just the words.
The company says the model has eliminated some of the reality-breaking glitches that gave earlier avatars away, such as the infamous problem of an avatar smiling while hearing bad news. Demonstration clips show the system teaching a participant how to solve a Rubik's Cube and playing a game of Simon Says, responding to visual cues as they happen. On NVIDIA's VideoFDB benchmark for video generation, Tavus reports Griffin scored 3.83 out of 5, against 3.92 for a human reference and 2.80 for the next-highest published system.
The unsettling part is not that the avatar fooled nearly half the room. It is that the fooled half felt 79 percent sure they were talking to a real person.
Why it matters
Griffin's Video Turing Test, by the numbers
Tavus's own results from live one-minute video calls, with a control stack for comparison.
Note: Figures are approximate, reported by Tavus.
Tavus is pitching Griffin as infrastructure for the next wave of human-machine interaction: tutors for students in schools, interviewers, customer service agents, and companions for the elderly. Those are real, plausible uses, and the company clearly believes face-to-face AI will follow the same path as text chatbots, from novelty to everyday utility.
But the same realism that makes a good tutor makes a dangerous impostor. Video calls have become one of the last trusted channels for identity verification, from remote job interviews to bank customer checks. A 48 percent misidentification rate under friendly conditions is a warning label: visual identity on a call is no longer self-evidently human. Impersonation fraud, social engineering, and non-consensual synthetic media all get harder to detect when the face on the screen breathes, hesitates, and interrupts like a person. Disclosure rules, the requirement that people be told they are interacting with AI, matter more with every step down this road.
What comes next
The claims are Tavus's, and the most important next step is independent verification. A peer-reviewed replication with adversarial interviewers, longer calls, and a larger sample would tell us how much of the 48 percent survives scrutiny. Competitors will certainly try; the gap between Griffin and the 2.4 percent control stack is the kind of lead that invites challengers.
Regardless of where the final number lands, the direction is clear. Real-time, photorealistic conversation partners are moving from research demos to products, and the threshold for convincing is lower than most of us assumed. The right question is no longer whether an avatar can pass for human in a short, friendly chat. It is what we do about a world where it usually can.
0 Comments